When a language model returns engineering quantities with the status "solved", software that trusts it passes them on, even when the requested design is physically…When a language model returns engineering quantities with the status "solved", software that trusts it passes them on, even when the requested design is physically impossible.
Feeding a pretrained language model the expected embedding of its own next-token distribution turns it into a discrete-time dynamical system with continuous states.Feeding a pretrained language model the expected embedding of its own next-token distribution turns it into a discrete-time dynamical system with continuous states. Across Qwen2.5, OLMo-2 and Llama-3 models from 0.
AI agents increasingly act as analysts whose decision can often be cast as hypothesis tests. Classical tests control the Type I error rate, the probability of rejecting a…AI agents increasingly act as analysts whose decision can often be cast as hypothesis tests. Classical tests control the Type I error rate, the probability of rejecting a true null hypothesis, for fixed procedures.
Generalist robot policies benefit from large-scale visual pretraining but often struggle with contact-rich dexterous manipulation, where force, compliance, and incipient…Generalist robot policies benefit from large-scale visual pretraining but often struggle with contact-rich dexterous manipulation, where force, compliance, and incipient slip are hard to observe from images.
Gerardo Adesso, Ludovico Lami, Vittorio Giovannetti
The classical capacity of a noisy optical channel is the maximum rate at which information can be transmitted reliably, given a constraint on the mean input energy.The classical capacity of a noisy optical channel is the maximum rate at which information can be transmitted reliably, given a constraint on the mean input energy.
The Model Context Protocol (MCP) standardizes how AI agents invoke external tools. MCP servers expose tools through a declared contract consisting of a name, description…The Model Context Protocol (MCP) standardizes how AI agents invoke external tools. MCP servers expose tools through a declared contract consisting of a name, description, and argument schema.
Sofya Raskhodnikova, Adam Smith, Connor Wagaman et al.
We study the problem of approximately counting subgraphs under local node differential privacy (LNDP), a recently introduced model that enforces strong privacy guarantees…We study the problem of approximately counting subgraphs under local node differential privacy (LNDP), a recently introduced model that enforces strong privacy guarantees in analyses of distributed social networks.
Given a joint distribution PXY on a finite alphabet, the information bottleneck method seeks a representation T of X that is as informative as possible about Y while…Given a joint distribution PXY on a finite alphabet, the information bottleneck method seeks a representation T of X that is as informative as possible about Y while compressing X, where T and Y are conditionally independent given…
Bingbing Hu, Tomasz Kociumaka, Jakob Nogler et al.
Tree edit distance (TED), the analog of string edit distance (ED) for hierarchical data, is the minimum number of node insertions, deletions, and substitutions…Tree edit distance (TED), the analog of string edit distance (ED) for hierarchical data, is the minimum number of node insertions, deletions, and substitutions transforming one labeled rooted ordered tree into another.
Step-level guards decide, before each tool call, whether an agent's next action is safe given the user's request and the trajectory so far.Step-level guards decide, before each tool call, whether an agent's next action is safe given the user's request and the trajectory so far.
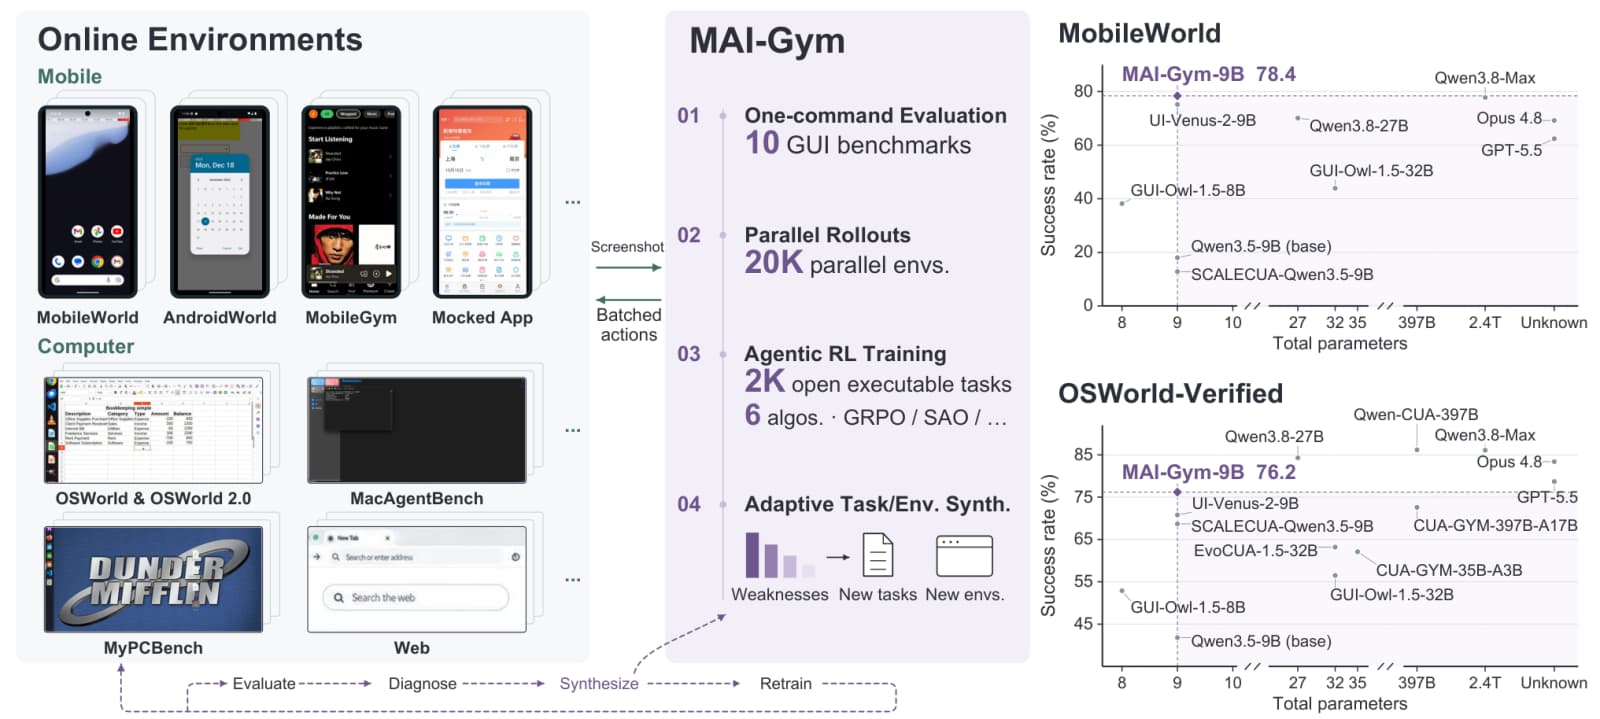
Computer use has reached a turning point: the focus is expanding from GUI-only interaction to systems that complete tasks on users' computers through visual and…Computer use has reached a turning point: the focus is expanding from GUI-only interaction to systems that complete tasks on users' computers through visual and programmatic interfaces.
Current humanoid dexterous manipulation remains largely confined to end-effectors and simple grasps, falling short of humans' ability to engage the entire body by bracing…Current humanoid dexterous manipulation remains largely confined to end-effectors and simple grasps, falling short of humans' ability to engage the entire body by bracing and sliding bulky objects against the arms and torso.
Liangjie Huang, Henry Peng Zou, Wei-Chieh Huang et al.
LLM systems increasingly rely on groups of agents that discuss, critique, and check one another, assuming that peers will catch individual errors.LLM systems increasingly rely on groups of agents that discuss, critique, and check one another, assuming that peers will catch individual errors. We test this assumption against a minimal adversary.
The proof improved running-time guarantees for all the graph problems studied in earlier work by Kratsch and Spinrad, essentially matching conditional limits.The proof improved running-time guarantees for all the graph problems studied in earlier work by Kratsch and Spinrad, essentially matching conditional limits.
Daniela Baiamonte, Kamyar Zeinalipour, Elena Fano et al.
Supervised fine-tuning datasets remain overwhelmingly English-centric and commercially restricted, as their content is frequently generated by proprietary models whose…Supervised fine-tuning datasets remain overwhelmingly English-centric and commercially restricted, as their content is frequently generated by proprietary models whose terms of service forbid training competing systems.
Multimodal large language models (MLLMs) can act unsafely when individually benign images and texts are interpreted jointly.Multimodal large language models (MLLMs) can act unsafely when individually benign images and texts are interpreted jointly.
Long-context language models support ever longer context windows, and evaluations typically treat context length as the main indicator of difficulty.Long-context language models support ever longer context windows, and evaluations typically treat context length as the main indicator of difficulty.
Zhang Xiaofeng, Samuel Lavoie, Nicolas Beltran-Velez et al.
Discrete image generators learn the distribution of tokens produced by an image tokenizer. These token representations should be easy for generators to model, not merely…Discrete image generators learn the distribution of tokens produced by an image tokenizer. These token representations should be easy for generators to model, not merely enable faithful image reconstruction.
Language priors in MLLMs can override visual evidence, impairing visual perception. Existing benchmarks assume shared priors across models and rely solely on accuracy.Language priors in MLLMs can override visual evidence, impairing visual perception. Existing benchmarks assume shared priors across models and rely solely on accuracy.
Johannes Knittel, Alec Helbling, Hanspeter Pfister
Weight quantization below four bits shrinks memory and bandwidth at a perplexity that looks acceptable, but often at the cost of factual knowledge and task accuracy.Weight quantization below four bits shrinks memory and bandwidth at a perplexity that looks acceptable, but often at the cost of factual knowledge and task accuracy.
Mohsinul Kabir, Md. Tariquzzaman, Karam S. R. Elradie et al.
Existing safety benchmarks rely largely on synthetic prompts with loosely grounded taxonomies and offer little focused analysis of severe crime categories.Existing safety benchmarks rely largely on synthetic prompts with loosely grounded taxonomies and offer little focused analysis of severe crime categories.
Data agents use code to process heterogeneous files and derive analytical insights. Scaling their training faces costly environment curation, privacy and…Data agents use code to process heterogeneous files and derive analytical insights. Scaling their training faces costly environment curation, privacy and intellectual-property restrictions, and difficulty verifying open-ended…
Brian B. Moser, Stanislav Frolov, Tobias C. Nauen et al.
With the rise of large language models, agentic systems are becoming increasingly autonomous, as they write code, call tools, revise prompts, and propose modifications to…With the rise of large language models, agentic systems are becoming increasingly autonomous, as they write code, call tools, revise prompts, and propose modifications to their own components.
Kolmogorov-Arnold networks (KANs) have a dimension-independent approximation exponent when the target admits a sufficiently smooth representation by univariate edge…Kolmogorov-Arnold networks (KANs) have a dimension-independent approximation exponent when the target admits a sufficiently smooth representation by univariate edge functions.
Existing deepfake detection models are built upon manipu- lated images that are tampered with either exclusively fully swapped or fully synthesised faces, which leads us…Existing deepfake detection models are built upon manipu- lated images that are tampered with either exclusively fully swapped or fully synthesised faces, which leads us to an open question: Can off-the-shelf deepfake models…
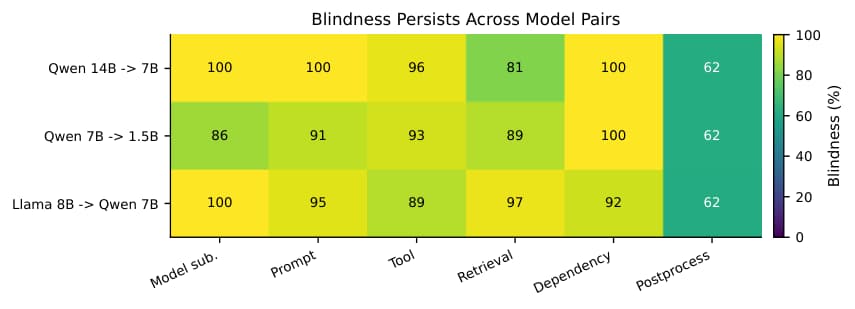
Large language model (LLM) agents now fix software, operate computers and serve customers, but their harnesses, the programs that run them, call a large LLM at every…Large language model (LLM) agents now fix software, operate computers and serve customers, but their harnesses, the programs that run them, call a large LLM at every step, which makes long tasks slow and costly.
Detailed captions transfer visual information into vision-language model supervision, but quality is easily conflated with length: long single-pass outputs still miss…Detailed captions transfer visual information into vision-language model supervision, but quality is easily conflated with length: long single-pass outputs still miss small objects, text, and spatial relations or promote uncertain…
Multimodal document retrieval-augmented generation (RAG) has focused largely on retrieval, yet its answers depend on how well a vision-language model reads the retrieved…Multimodal document retrieval-augmented generation (RAG) has focused largely on retrieval, yet its answers depend on how well a vision-language model reads the retrieved pages.
Large language models (LLMs) often make discrete decisions, such as flagging phishing or escalating to a human.Large language models (LLMs) often make discrete decisions, such as flagging phishing or escalating to a human. System-1 models, such as Jev and the OpenAI Decisions API, return probabilities over options in a single forward pass…
Latent chain-of-thought replaces written reasoning steps with continuous hidden states, giving models additional steps to compute before answering.Latent chain-of-thought replaces written reasoning steps with continuous hidden states, giving models additional steps to compute before answering. It remains unclear what computation these steps actually perform.
Dual-system vision-language-action (VLA) models pair a high-frequency fast policy with a slow, expensive module, and published trigger mechanisms for invoking it lack a…Dual-system vision-language-action (VLA) models pair a high-frequency fast policy with a slow, expensive module, and published trigger mechanisms for invoking it lack a shared objective, measured costs, and any standard separating…
On-screen text can describe what a video shows, or it can frame what the video is supposed to mean. Current benchmarks treat both alike, testing whether a model can read…On-screen text can describe what a video shows, or it can frame what the video is supposed to mean. Current benchmarks treat both alike, testing whether a model can read the text rather than whether it should trust it.
Mean acceptance of tampered outputs rose from 88.6% for rule-based scorers to 94.1% for GPT-5-nano on the benchmark.Mean acceptance of tampered outputs rose from 88.6% for rule-based scorers to 94.1% for GPT-5-nano on the benchmark. The researchers introduced DIB-Bench, a benchmark testing whether evaluators detected tampering with the…
Label-free evaluation methods, such as self-consistency filtering, majority-vote aggregation, and agreement-based reliability scoring, rely on an implicit assumption that…Label-free evaluation methods, such as self-consistency filtering, majority-vote aggregation, and agreement-based reliability scoring, rely on an implicit assumption that consistency can serve as a proxy for correctness when…
We study a protocol-level reaction leakage in CKKS deployments where public coefficient-to-slot (C2S) evaluation keys are combined with a client's 1-bit validity…We study a protocol-level reaction leakage in CKKS deployments where public coefficient-to-slot (C2S) evaluation keys are combined with a client's 1-bit validity response.
Sai Varun Kodathala, Prashanth Pollishetty, Jaylen Cargill
AI agents now pause for approval before they send money, delete files or email outsiders, and that approval is usually treated as a second factor.AI agents now pause for approval before they send money, delete files or email outsiders, and that approval is usually treated as a second factor.
The twin goals of privacy-preserving federated learning (FL) – harnessing distributed data while protecting the parties who contribute it – demands three properties…The twin goals of privacy-preserving federated learning (FL) – harnessing distributed data while protecting the parties who contribute it – demands three properties: model privacy, data privacy, and integrity.
After 104 hours, the agents’ model averaged 48.2 on hidden tests, against 47.9 for the official instruction-trained version and 9.2 for the starting model.After 104 hours, the agents’ model averaged 48.2 on hidden tests, against 47.9 for the official instruction-trained version and 9.2 for the starting model.
MAI-Gym supported ten established tests and 20,000 simultaneous software environments, using a shared process to run agents during training and testing.MAI-Gym supported ten established tests and 20,000 simultaneous software environments, using a shared process to run agents during training and testing.
Reinforcement learning with self-generated labels, such as majority vote over a model's own samples, often recovers most of the gain of training with verifiable rewards.Reinforcement learning with self-generated labels, such as majority vote over a model's own samples, often recovers most of the gain of training with verifiable rewards.