Indirect prompt injection (IPI) hides adversarial instructions in content that large language model (LLM) agents read at runtime.Indirect prompt injection (IPI) hides adversarial instructions in content that large language model (LLM) agents read at runtime. As agents compose heterogeneous capability units, including Tools, MCP servers, and Skills, the…
Behavioral watermarking embeds an owner identifier in an LLM agent's high-level action choices, giving provenance without touching output tokens.Behavioral watermarking embeds an owner identifier in an LLM agent's high-level action choices, giving provenance without touching output tokens. Prior agent watermarks break in two ways.
Safety alignment in Large Language Models (LLMs) remains vulnerable to backdoor attacks. Existing LLM backdoors are almost all input-centric: activation depends on…Safety alignment in Large Language Models (LLMs) remains vulnerable to backdoor attacks. Existing LLM backdoors are almost all input-centric: activation depends on explicit trigger patterns in the user input, so modern guardrails…
Network traffic analysis is central to network security, spanning tasks from intrusion detection to encrypted traffic classification.Network traffic analysis is central to network security, spanning tasks from intrusion detection to encrypted traffic classification. Existing approaches either train task-specific models that generalize poorly or rely on costly…
Abhinav Sudhakar Dubey, Scott Sirri, Vaggos Chatziafratis et al.
While open-weight models have enjoyed steady progress in capabilities and wide adoption across multiple domains, their safety remains an important concern.While open-weight models have enjoyed steady progress in capabilities and wide adoption across multiple domains, their safety remains an important concern.
A study showed that standard security benchmarks misread accuracy drops as backdoor removal costs, and presented a tool that measures defenses on clean twin models.A study showed that standard security benchmarks misread accuracy drops as backdoor removal costs, and presented a tool that measures defenses on clean twin models.
Joshua Kalyanapu, Darsh Asher, Kaushal Mhapsekar et al.
Membership is the root privacy primitive in machine learning: to date, no hardware-based out-of-distribution detection on black-box models has been demonstrated against…Membership is the root privacy primitive in machine learning: to date, no hardware-based out-of-distribution detection on black-box models has been demonstrated against constant-time, static neural networks with masked confidence.
As Large Language Models (LLMs) gain tool use capabilities such as web search, they can retrieve and cross-reference public information, creating privacy risks beyond…As Large Language Models (LLMs) gain tool use capabilities such as web search, they can retrieve and cross-reference public information, creating privacy risks beyond memorization.
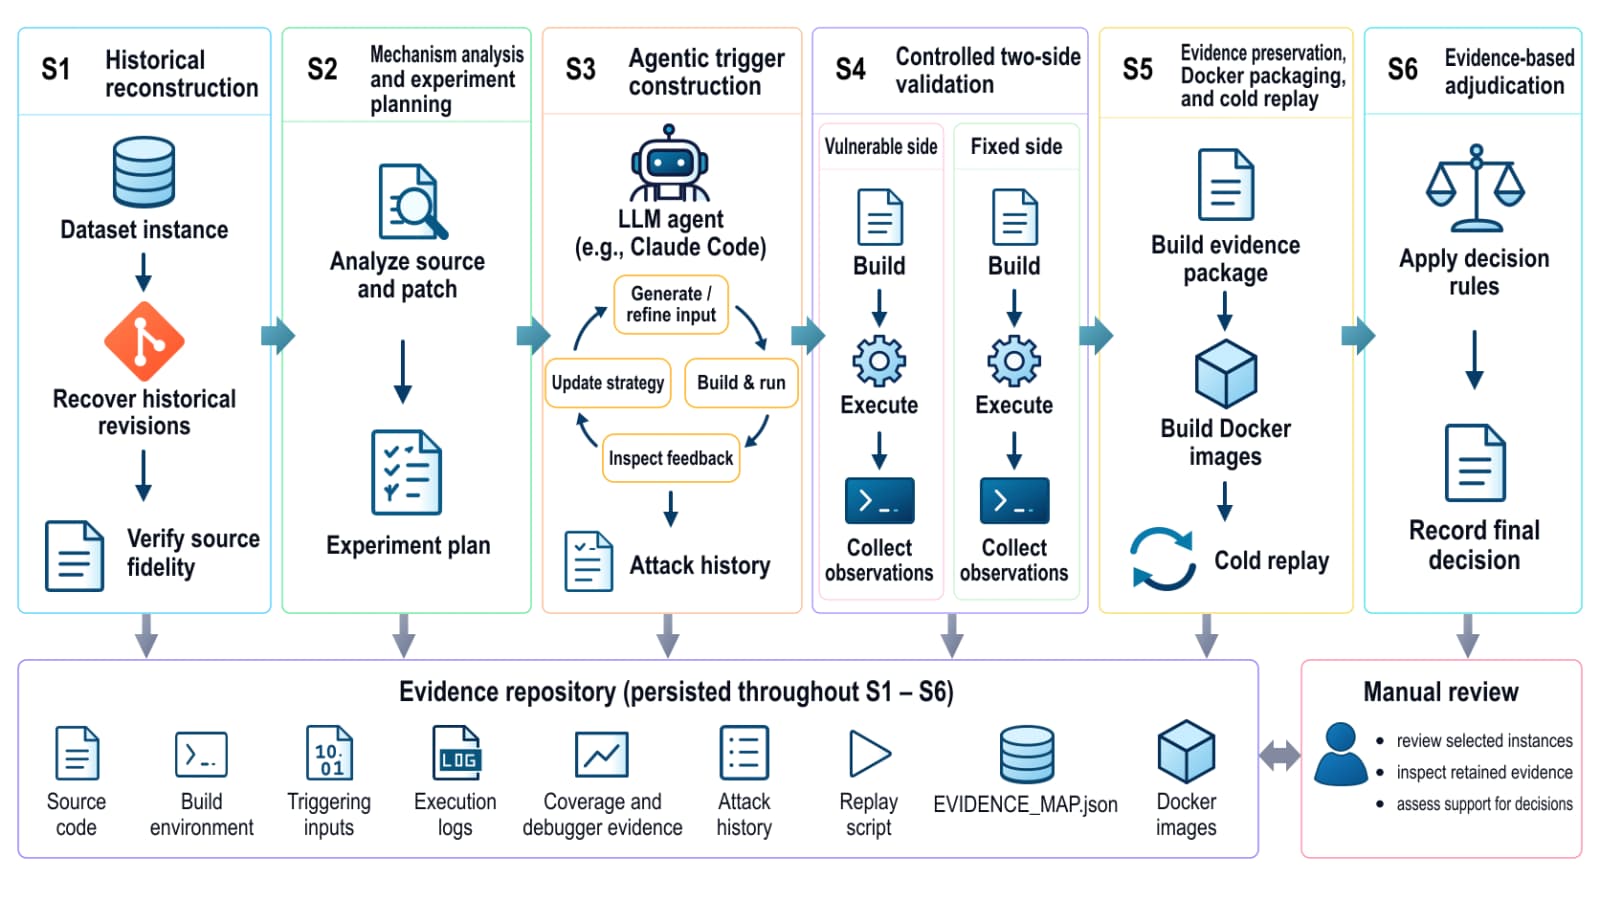
An auditing framework tested 35,849 code instances across three datasets, confirming 57.2% of vulnerability labels and correcting 19.0% by executing flaw-triggering…An auditing framework tested 35,849 code instances across three datasets, confirming 57.2% of vulnerability labels and correcting 19.0% by executing flaw-triggering tests.
Text watermarking helps identify AI-generated content, but its effect on factual reliability remains underexplored.Text watermarking helps identify AI-generated content, but its effect on factual reliability remains underexplored. In this paper, we study watermarking hallucination: factual errors induced or amplified by watermarking even when…
Is agentic memory robust against stealthy steganographic attacks? We carry out a large-scale red-teaming exercise to test whether agents can encode attacker-controlled…Is agentic memory robust against stealthy steganographic attacks? We carry out a large-scale red-teaming exercise to test whether agents can encode attacker-controlled strings in one session and recover them in another without…
Kai-Min Chung, Tzu-Hsiang Huang, Wei-Hsiang Hung et al.
We present a unified framework for upgrading a broad class of cryptographic primitives to support constant-rate certified deletion.We present a unified framework for upgrading a broad class of cryptographic primitives to support constant-rate certified deletion. Previous constructions require a linear number of qubits per encrypted bit of certified-deletable…
Neeraj Karamchandani, Piyush Nagasubramaniam, Xinhong Xie et al.
Security benchmarks for LLM-based agents often report the attack success rate (ASR) as a measure of model robustness and use these scores to compare different models and…Security benchmarks for LLM-based agents often report the attack success rate (ASR) as a measure of model robustness and use these scores to compare different models and defense mechanisms, assuming that they describe the security…
LLM agents increasingly screen tool outputs with small prompt-injection detectors, and teams choose among detectors by their scores on public benchmarks.LLM agents increasingly screen tool outputs with small prompt-injection detectors, and teams choose among detectors by their scores on public benchmarks. We ask whether those scores predict how a detector behaves inside an agent.
Giulio Zingrillo, Hanna Foerster, Ilia Shumailov et al.
Modern Computer Use Agents (CUAs) directly interact with graphical user interfaces and execute third-party web tools, exposing them to indirect prompt injection across…Modern Computer Use Agents (CUAs) directly interact with graphical user interfaces and execute third-party web tools, exposing them to indirect prompt injection across every rendered page and tool response.
Differential privacy (DP) admits several notions, but the choice among them may affect both privacy analysis and utility.Differential privacy (DP) admits several notions, but the choice among them may affect both privacy analysis and utility. In this paper, we consider four mainstream curve-based privacy notions within a unified…
Ryuichi Yamafuji Lun, Jingzhen Wang, Shreyas Kolte et al.
Inter-agent communication is central to Large Language Model Multi-Agent Systems (LLM-MAS), but it introduces an underexplored vulnerability: Agent-in-the-Middle (AiTM)…Inter-agent communication is central to Large Language Model Multi-Agent Systems (LLM-MAS), but it introduces an underexplored vulnerability: Agent-in-the-Middle (AiTM) attacks that manipulate messages in transit without…
LLM agents use skills to improve performance on specialized tasks. To complete a user request, an agent may invoke several skills in sequence, allowing information…LLM agents use skills to improve performance on specialized tasks. To complete a user request, an agent may invoke several skills in sequence, allowing information produced under one skill to guide the next.
Safety routers send each request to one of several models and are judged against the best single model.Safety routers send each request to one of several models and are judged against the best single model. A major routing benchmark picks that comparator on the evaluation data.
AI agents that control wallets read attacker-reachable content, so they can be steered into proposing harmful transactions.AI agents that control wallets read attacker-reachable content, so they can be steered into proposing harmful transactions. The usual last line of defense is a pre-signing check: a static allowlist, an LLM reviewer, or a…
LLM agents increasingly rely on installable skills, which are packages of instructions, code, and resources that equip them with task-specific capabilities and, once…LLM agents increasingly rely on installable skills, which are packages of instructions, code, and resources that equip them with task-specific capabilities and, once installed, can be automatically invoked across subsequent user…
Modern AI coding-agent harnesses (Claude Code, Codex CLI, Cursor) rest their security boundary on a largely unexamined assumption: that the action A a human approves is…Modern AI coding-agent harnesses (Claude Code, Codex CLI, Cursor) rest their security boundary on a largely unexamined assumption: that the action A a human approves is the same action A' the harness executes, where A is fixed by…
Video Multimodal Large Language Models (Video-MLLMs) support reasoning over video inputs, yet remain vulnerable to jailbreak attacks that elicit policy-violating…Video Multimodal Large Language Models (Video-MLLMs) support reasoning over video inputs, yet remain vulnerable to jailbreak attacks that elicit policy-violating responses.
This technical report presents an alignment evaluation developed and performed by the UK AI Security Institute for assessing whether advanced AI systems take unsanctioned…This technical report presents an alignment evaluation developed and performed by the UK AI Security Institute for assessing whether advanced AI systems take unsanctioned actions outside the scope of their assigned task.